Choosing DDR5 memory for a data center is not simply a matter of buying the newest module. It involves workload analysis, platform compatibility, power limits, and long-term expansion plans. A database server may need high capacity, while an artificial intelligence cluster may prioritize bandwidth. The wrong choice can leave expensive processors waiting beside underused memory.
Sanjay Mehrotra, president and CEO of Micron, has described DDR5 as “a critical technology to enable the data center of the future.” That observation remains practical. DDR5 memory for data center environments can increase bandwidth, improve memory efficiency, and support demanding applications. However, performance gains depend on the entire system. The processor, motherboard, firmware, cooling design, and memory configuration must work together.
Small details matter.
A poorly balanced installation may create bottlenecks despite impressive specifications. Capacity also deserves careful attention. More memory is not automatically better if the workload cannot use it. Error correction, module quality, power consumption, and supplier reliability should receive equal consideration. These factors affect uptime, maintenance schedules, and operating costs.
This guide presents seven practical tips for choosing DDR5 memory for data center deployments. It examines compatibility, capacity, speed, ECC protection, power requirements, thermal conditions, and future scalability. The recommendations reflect real purchasing pressures, including limited budgets and uncertain growth. No single configuration fits every facility. That is the difficult part—and sometimes the most overlooked one.
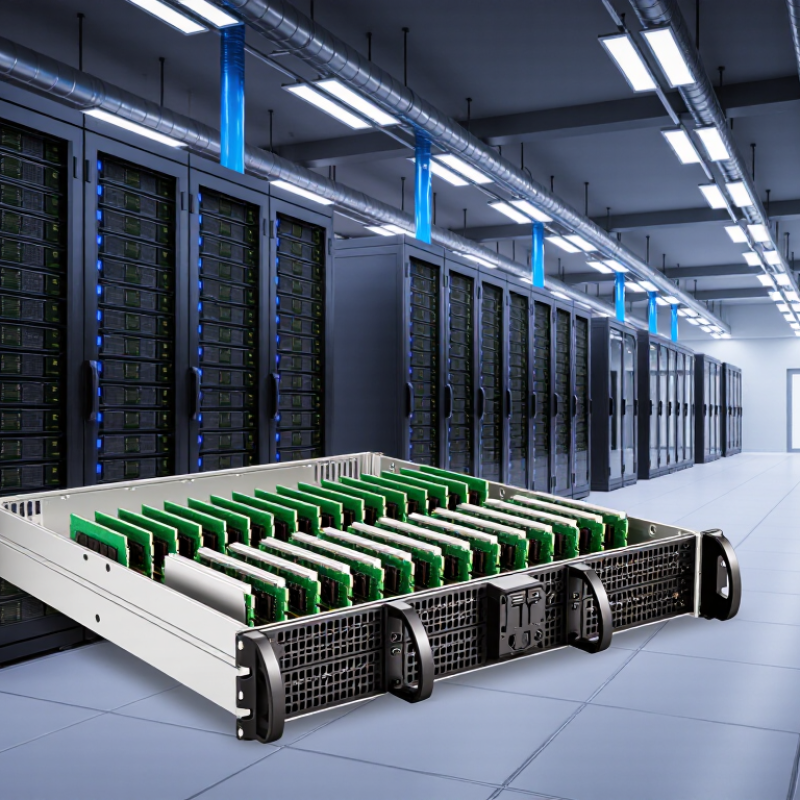
Measure the workload before selecting capacity. Transaction databases need predictable latency, while analytics and AI pipelines consume bandwidth quickly. DDR5’s JEDEC JESD79-5 standard supports data rates up to 6,400 MT/s, but higher speed alone will not fix poor workload mapping. Record memory bandwidth, capacity, page faults, and CPU utilization during peak hours.
Size for real concurrency, not average usage. A database server showing 65% memory utilization may still fail during monthly reporting. Keep practical headroom for virtual machines, operating-system caching, and maintenance migration.
Match channels and modules to the platform’s memory architecture. Uneven population can reduce bandwidth and complicate future expansion. This detail is easy to miss.
Treat reliability as a workload requirement. Uptime Institute’s 2023 Annual Outage Analysis reported that 25% of significant outages cost more than one million dollars. For revenue-critical systems, choose error-correcting memory and verify platform support, fault handling, and replacement procedures.
Check power and thermal limits. Higher-density modules can reduce slot usage, yet they may increase cooling pressure.
Validate memory choices with replayed production traces, not only synthetic benchmarks. A neat sizing spreadsheet can still be wrong.
The SPEC CPU 2017 documentation also warns that benchmark results depend heavily on configuration, compiler settings, and system design. Re-test after firmware updates, virtualization changes, and workload growth. That discipline makes DDR5 selection evidence-based rather than optimistic.
7 Tips for Choosing DDR5 Memory for Data Centers
Capacity determines how much data a server can keep close to the processor. Speed indicates how quickly each memory transfer occurs. Bandwidth reflects the total data moving across active channels. These measures overlap, but they are not interchangeable. More speed cannot rescue a server that constantly swaps data to storage. More capacity cannot fix narrow channel usage.
Match capacity to the workload. Large databases, virtual machines, and analytics platforms usually need generous memory headroom. Measure peak usage, not the average shown during quiet hours. Leave room for operating-system overhead and future growth. In testing, a 512 GB configuration may appear sufficient, yet memory pressure can rise sharply after adding several virtual machines. My first estimate was wrong because I ignored burst activity.
Compare rated speed with real platform support. The processor, motherboard design, firmware, and DIMM population can limit the practical result. Populate memory channels evenly when possible. An uneven layout may reduce usable bandwidth and complicate troubleshooting. Check latency, error-correction support, thermal limits, and validated capacity per socket. Higher transfer rates can increase power consumption, too. That trade-off deserves measurement. Use workload tests that record throughput, latency, power draw, and error events. A balanced DDR5 configuration often delivers more dependable performance than the fastest available modules.
7 Tips for Choosing DDR5 Memory for Data Centers
When selecting DDR5 memory, treat ECC as a protection layer, not a marketing checkbox. On-die ECC corrects some internal chip errors, but it does not replace system-level ECC. Confirm that the memory module supports error correction across the data path. Check whether the server platform supports registered modules, memory sparing, patrol scrubbing, and demand scrubbing. These features can reduce downtime when a fault appears during heavy workloads.
Reliability also depends on the operating environment. Measure inlet temperature, airflow, and memory power during sustained testing. A module may pass a short benchmark yet show corrected errors after hours of database activity. Review firmware settings and error logs regularly. Clear records hide patterns. Ask for documented failure-rate testing, qualification procedures, and lifecycle support. Independent validation is valuable, especially when systems will run continuously in remote racks.
Data protection requires more than ECC. Match memory capacity and rank structure with the server’s supported configuration. Uneven population can reduce performance or disable protection features. Test boot recovery, error reporting, and replacement procedures before deployment. A spare module should be available, but spare capacity alone cannot repair corrupted application data. Backups, replication, and access controls still matter. No checklist is perfect. Teams sometimes trust specifications too quickly and discover compatibility problems only after installation. A small pilot, followed by stress testing and review, can expose those weaknesses before they become expensive outages.
DDR5 memory can improve server throughput, but compatibility should lead the purchasing decision. Check the processor’s supported memory speed, maximum capacity, channel layout, and registered or load-reduced DIMM requirements. JEDEC’s JESD79-5 standard defines DDR5 operation from 3,200 MT/s, with a nominal 1.1-volt supply. However, a faster module may downclock when the server firmware, CPU, or motherboard cannot support its profile. Verify the qualified vendor list, firmware version, rank layout, and error-correction support. Tiny details matter.
Power and heat deserve equal attention. The International Energy Agency reported that data centers used about 460 TWh of electricity worldwide in 2022, and demand could exceed 1,000 TWh by 2026. Memory is only one load, but hundreds of DIMMs can raise rack power and cooling requirements. Compare idle and sustained-load measurements, not only the module’s voltage rating. Ask for DIMM power data at your intended capacity. Then check airflow direction, inlet temperature, fan policy, and thermal throttling thresholds. A crowded rack changes the result.
Use seven practical checks: capacity, channels, speed, firmware, ECC, power, and temperature. Test a fully populated configuration before deployment. Monitor corrected errors and DIMM temperature during heavy workloads. A laboratory result may not survive a dusty, warm aisle. I would also leave thermal headroom rather than sizing to the stated limit; that judgment is easy to overlook, and it can prevent unstable operation later.
7 Tips for Choosing DDR5 Memory for Data Centers
Balance Memory Cost, Scalability, and Long-Term Performance
Start with the workload, not the memory label. Database servers, virtual machines, and analytics platforms use capacity differently. Measure peak usage, page faults, and memory bandwidth during real production cycles. A short benchmark can mislead. Longer observation is safer.
Compare cost per usable gigabyte, not cost per module. Higher-density modules may reduce slots and future expansion pressure. However, filling every slot today can limit tomorrow’s upgrades. Leave practical headroom. Check the platform’s supported capacity, channel layout, and error-correction features before purchasing. Balanced channels usually deliver steadier performance than a crowded, uneven design.
Plan for three to five years. Estimate data growth, virtual machine expansion, and software changes. Then test the proposed configuration under heat and sustained load. Power consumption matters because memory affects cooling requirements. Firmware validation and supplier quality records also deserve attention. In my experience, compatibility problems appear after routine updates, not during the first installation. Do not treat one successful boot as proof. Keep a small reserve budget for replacement modules and unexpected capacity needs. The cheapest choice can become expensive when labor, downtime, and redesign are included.
| No. | Selection Tip | Recommended Data Dimension | Reference Data | Why It Matters | Practical Action |
|---|---|---|---|---|---|
| 1 | Match capacity to workload demand | Installed memory per server and expected growth | Plan for current demand plus a capacity reserve of approximately 20% to 30%, depending on workload volatility. | Insufficient memory can cause paging, cache eviction, or reduced virtual-machine density, while excessive capacity increases acquisition cost. | Measure peak memory utilization for at least several representative workload cycles before selecting module sizes. |
| 2 | Choose the correct speed grade | Data-transfer rate and theoretical bandwidth | Common JEDEC DDR5 server speed grades include 4,800, 5,600, and 6,400 MT/s. A 64-bit channel provides approximately 38.4, 44.8, and 51.2 GB/s respectively. | Higher transfer rates can improve bandwidth-sensitive workloads, but actual performance also depends on the processor, memory-channel configuration, and workload access pattern. | Use the highest officially supported speed that provides measurable value; do not pay for unsupported or automatically downclocked modules. |
| 3 | Prioritize balanced channel population | Number of populated memory channels and modules per channel | Populate channels symmetrically whenever possible. A server with eight memory channels generally delivers better aggregate bandwidth when all eight channels are populated evenly than when only part of the channels are used. | Uneven population may reduce available bandwidth and can create avoidable capacity and performance bottlenecks. | Follow the platform memory population rules and select identical-capacity modules for matched positions. |
| 4 | Use server-grade reliability features | Module type, error correction, and fault coverage | Data-center platforms commonly use ECC Registered DIMMs. DDR5 also places a power-management IC on the module and includes on-die error correction, but on-die correction does not replace system-level ECC. | System-level ECC helps detect and correct certain memory errors that could otherwise cause data corruption or service interruption. | Confirm support for ECC Registered DIMMs, memory sparing, patrol scrubbing, and any required reliability modes in the server documentation. |
| 5 | Evaluate latency, not speed alone | CAS latency and first-word access time | Approximate CAS latency can be estimated as CL × 2,000 ÷ data rate. For example, DDR5-4,800 CL40 is about 16.7 ns, while DDR5-6,400 CL52 is about 16.3 ns. | A higher MT/s rating does not automatically guarantee lower access latency. Some workloads benefit more from latency than from peak bandwidth. | Compare complete speed-and-timing specifications under the same server configuration and benchmark representative applications. |
| 6 | Account for power and thermal density | Operating voltage, module count, and cooling load | Standard DDR5 operating voltage is typically 1.1 V, compared with 1.2 V for standard DDR4. Total memory power still increases with capacity, module count, speed, utilization, and airflow requirements. | Lower voltage does not guarantee lower total rack power when a server contains substantially more memory modules. | Estimate memory power at the planned module count and verify that chassis airflow and rack power budgets remain adequate. |
| 7 | Plan for lifecycle scalability and total cost | Upgrade flexibility, availability, and cost per usable gigabyte | Compare the complete cost of ownership: memory cost, unused slots, energy, downtime risk, support, and future expansion. Higher-density modules can preserve slots, while lower-density modules may offer a lower initial cost. | A low purchase price can become expensive if it limits future capacity upgrades or requires early platform replacement. | Reserve compatible slots where practical, standardize a small number of validated module configurations, and review a three-to-five-year expansion plan. |
Record capacity, bandwidth, page faults, and CPU use during peak hours. Quiet-hour averages can mislead. Use real workload data.
Several virtual machines may start together during monthly reporting. A server using 65% memory normally can still run out suddenly. Keep practical headroom.
No. Higher speed cannot repair narrow channel usage or frequent storage swapping. Measure throughput, latency, power, and error events. Fast is not automatically useful.
Follow the platform’s supported channel layout. Populate channels evenly when possible. Uneven placement may reduce bandwidth and complicate future expansion.
Reserve space for virtual machines, operating-system caching, maintenance migration, and workload growth. A 512 GB setup may appear adequate during testing. Burst activity can change that judgment.
Confirm system-level error correction and platform support for registered modules. Check memory sparing, patrol scrubbing, demand scrubbing, and error reporting. Internal chip correction is not enough.
Measure inlet temperature, airflow, and memory power during sustained workloads. Dense modules may save slots but increase cooling pressure. Short tests can hide heat-related errors.
Replay production traces instead of relying only on synthetic benchmarks. Retest after firmware, virtualization, or workload changes. My first estimate was wrong once. A small pilot can expose compatibility problems early.
Choosing DDR5 memory for data center environments requires a clear understanding of workload demands and future growth plans. Start by assessing whether applications prioritize high capacity, low latency, strong bandwidth, or a balanced combination. The right DDR5 memory for data center workloads should support virtualization, databases, analytics, and other services without creating performance bottlenecks. Compare module capacities, transfer speeds, and bandwidth carefully, while considering how memory channels and system architecture affect real-world results.
Reliability is equally important. Look for ECC support and data protection features that help detect and correct memory errors during continuous operation. Confirm compatibility with server platforms, processor requirements, firmware, and available memory slots before purchasing. Power consumption and thermal limits should also be reviewed because higher-performance modules may increase cooling demands. Finally, balance initial cost against scalability, maintenance needs, and long-term performance. A carefully planned DDR5 configuration can improve efficiency, reduce future upgrades, and provide dependable capacity as data center workloads continue to expand.
Vorynex